

Paramètres
- 588pages
- 21 heures de lecture
En savoir plus sur le livre
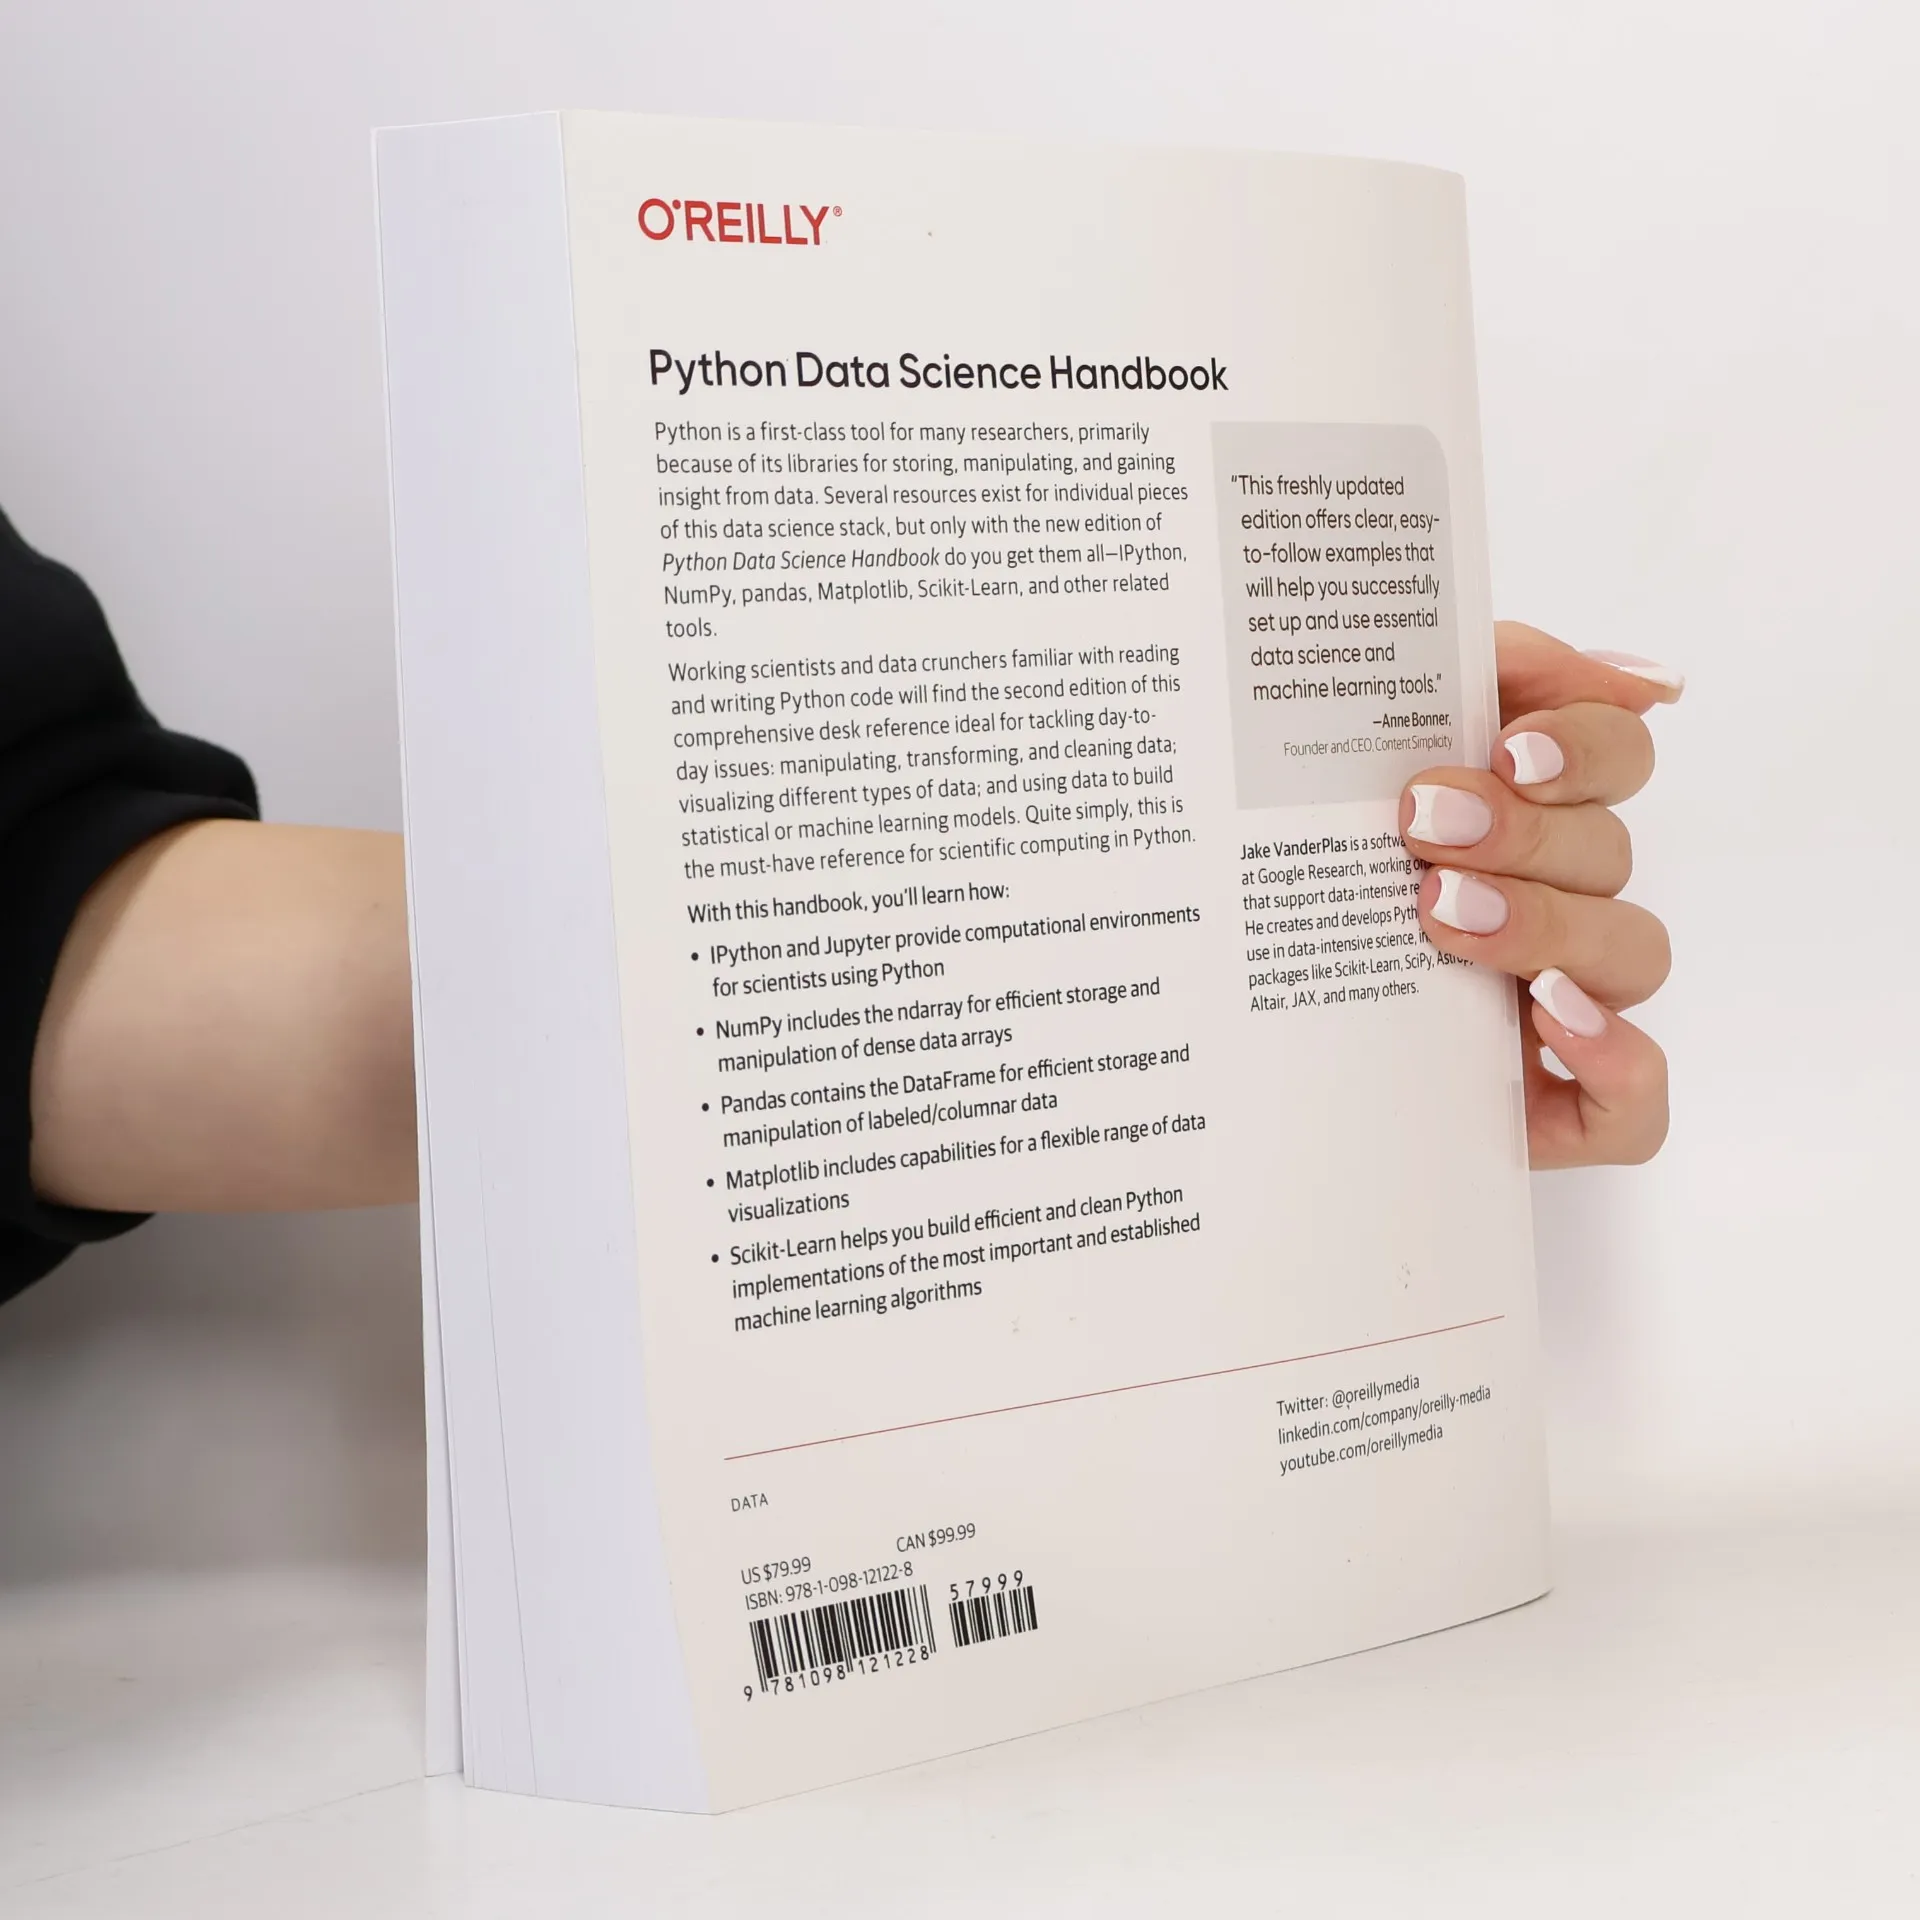
Python is a first-class tool for many researchers, primarily because of its libraries for storing, manipulating, and gaining insight from data. Several resources exist for individual pieces of this data science stack, but only with the new edition of Python Data Science Handbook do you get them all--IPython, NumPy, pandas, Matplotlib, scikit-learn, and other related tools. Working scientists and data crunchers familiar with reading and writing Python code will find the second edition of this comprehensive desk reference ideal for tackling day-to-day issues: manipulating, transforming, and cleaning data; visualizing different types of data; and using data to build statistical or machine learning models. Quite simply, this is the must-have reference for scientific computing in Python. With this handbook, you'll learn how: IPython and Jupyter provide computational environments for scientists using Python NumPy includes the ndarray for efficient storage and manipulation of dense data arrays Pandas contains the DataFrame for efficient storage and manipulation of labeled/columnar data Matplotlib includes capabilities for a flexible range of data visualizations Scikit-learn helps you build efficient and clean Python implementations of the most important and established machine learning algorithms
Achat du livre
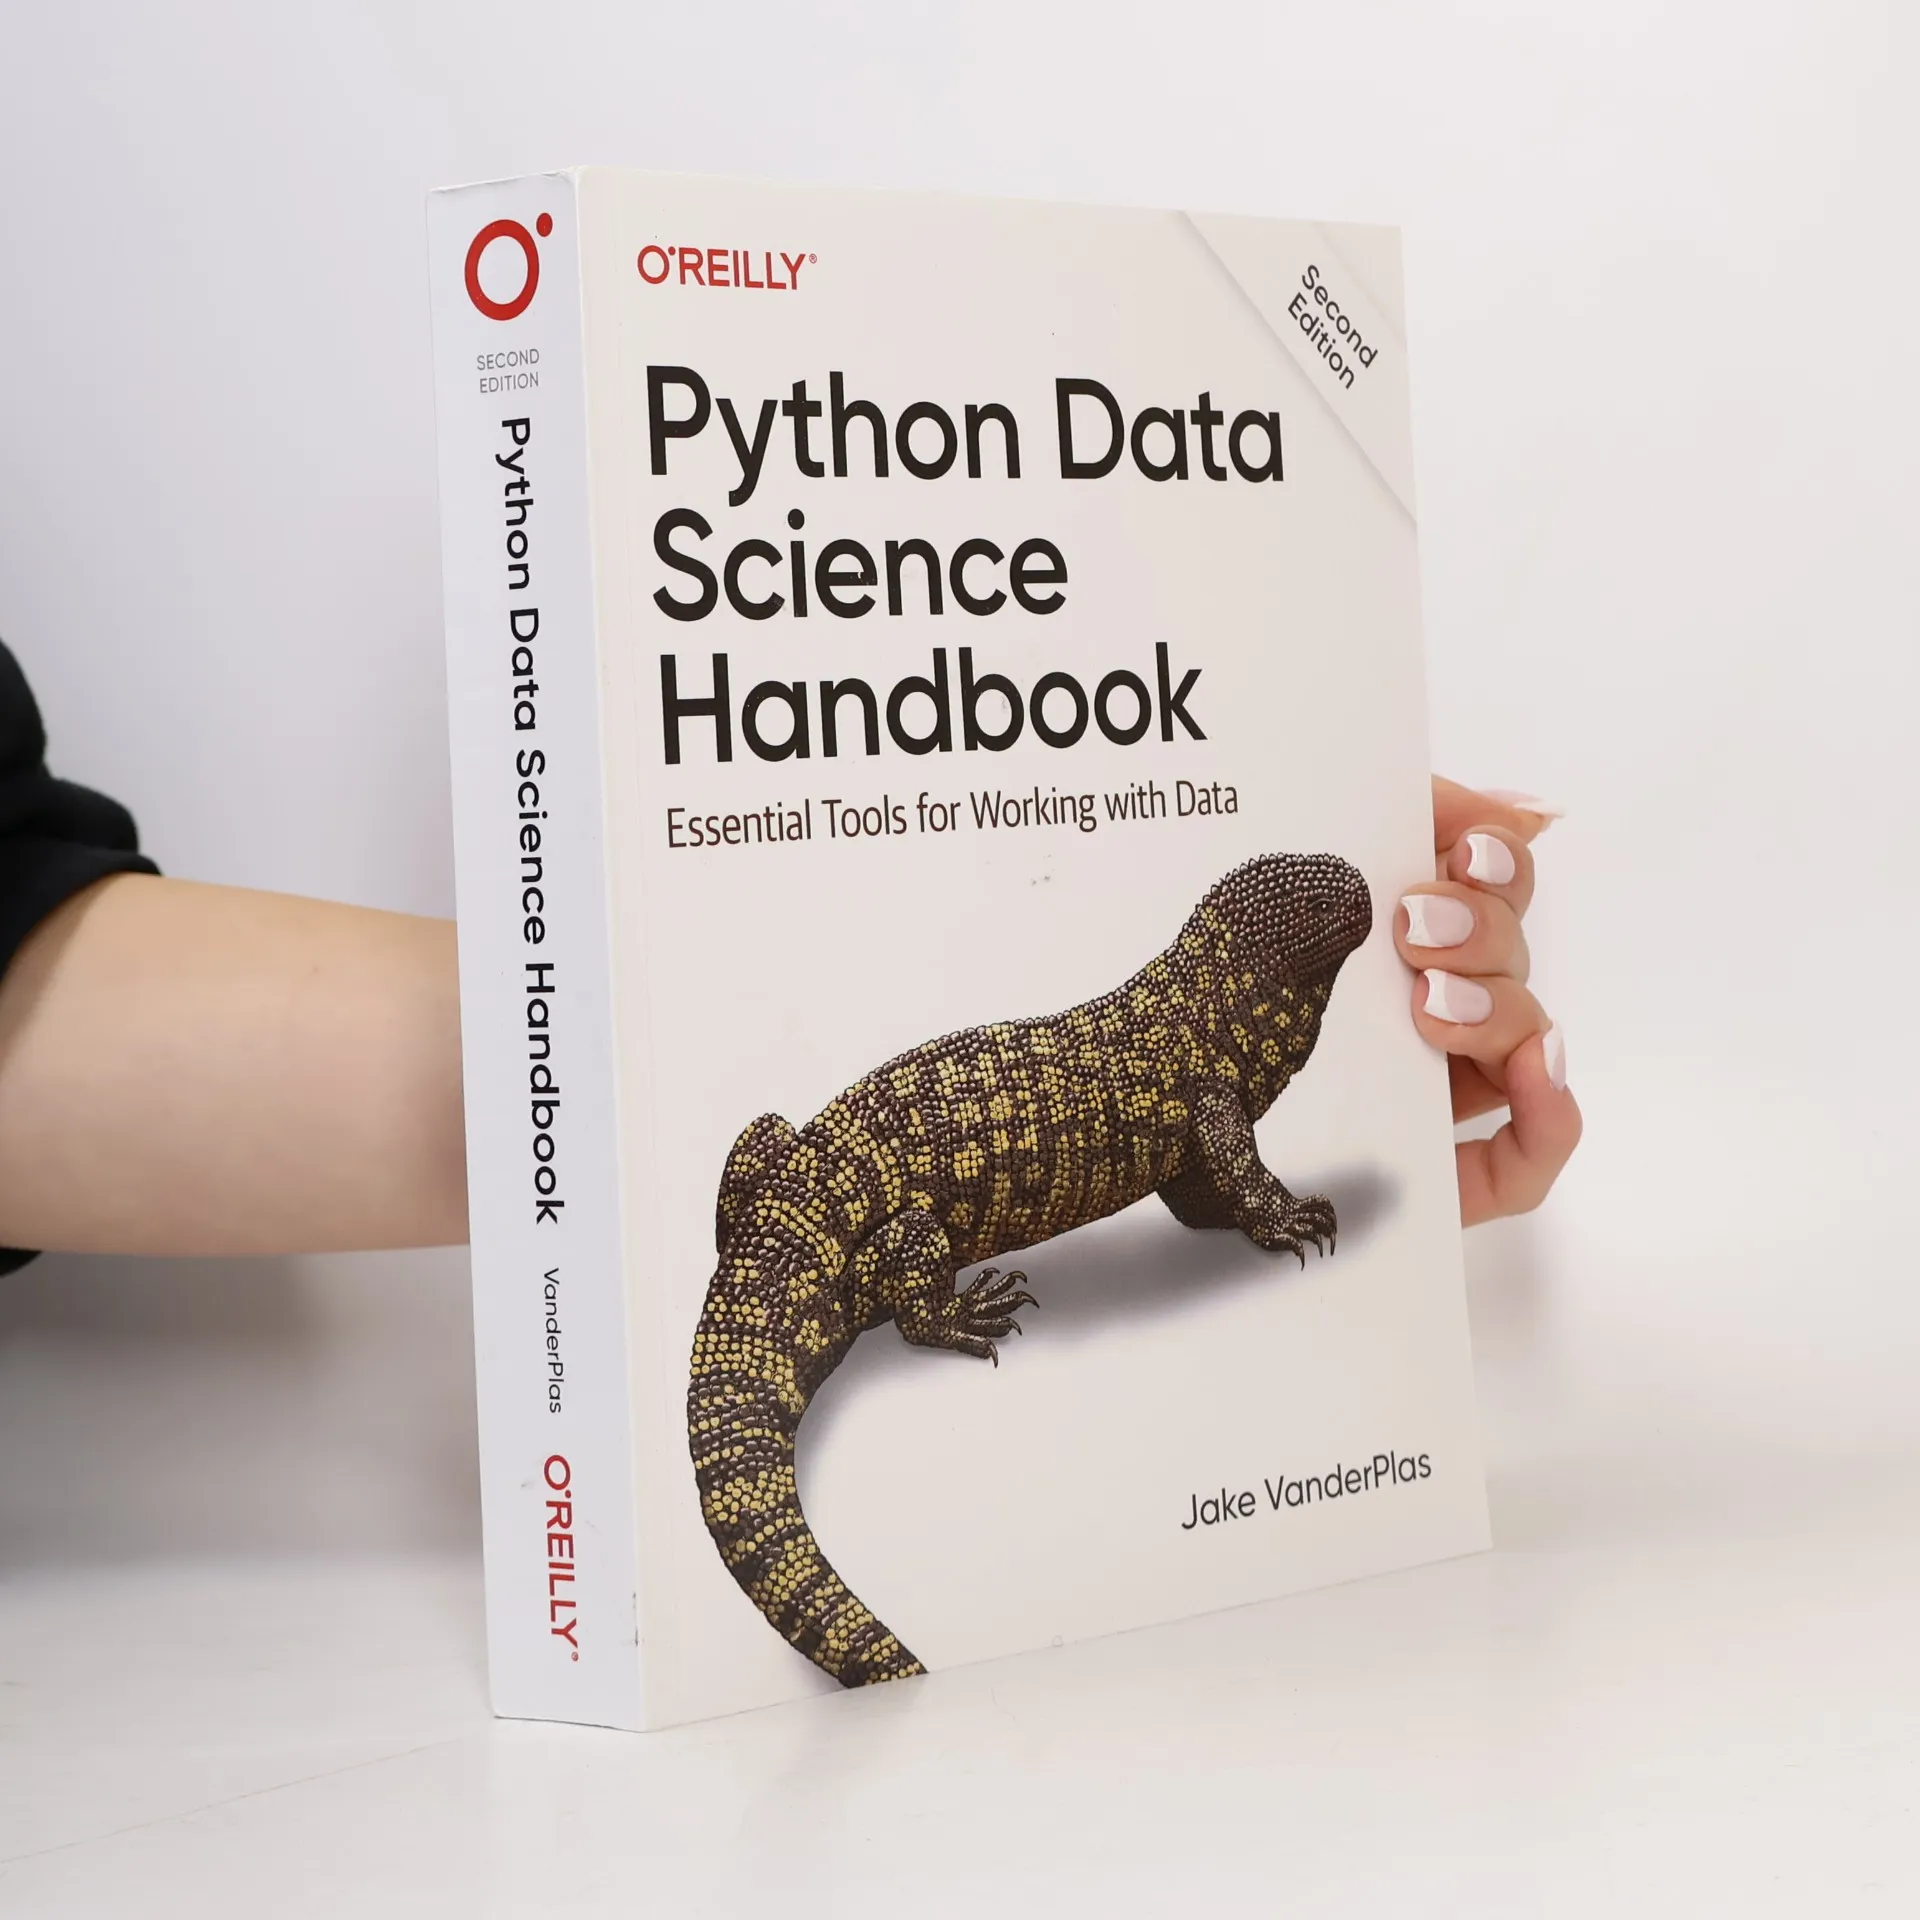
Python Data Science Handbook, Jake VanderPlas
- Langue

- Année de publication
- 2023
- Reliure
- (souple),
- État du livre
- Très bon
- Prix
- 43,99 €
Modes de paiement
Personne n'a encore évalué .
- Titre
- Python Data Science Handbook
- Sous-titre
- Essential Tools for Working with Data, Second Edition
- Langue
- Anglais
- Auteurs
- Jake VanderPlas
- Éditeur
- O'Reilly Media
- Publié
- 2023
- Format
- souple
- Pages
- 588
- ISBN10
- 1098121228
- ISBN13
- 9781098121228
- Séries
- Catégories
- Mots clés
- Manuels et guides, Architecture, Science, Technologie, Littérature spécialisée, Internet, Intelligence Artificielle, Création de sites web, Développement de logiciels, Base de données, Méthodologie, Traitement des données, Analyse de données, Apprentissage automatique, Open Source
- Description
- Python is a first-class tool for many researchers, primarily because of its libraries for storing, manipulating, and gaining insight from data. Several resources exist for individual pieces of this data science stack, but only with the new edition of Python Data Science Handbook do you get them all--IPython, NumPy, pandas, Matplotlib, scikit-learn, and other related tools. Working scientists and data crunchers familiar with reading and writing Python code will find the second edition of this comprehensive desk reference ideal for tackling day-to-day issues: manipulating, transforming, and cleaning data; visualizing different types of data; and using data to build statistical or machine learning models. Quite simply, this is the must-have reference for scientific computing in Python. With this handbook, you'll learn how: IPython and Jupyter provide computational environments for scientists using Python NumPy includes the ndarray for efficient storage and manipulation of dense data arrays Pandas contains the DataFrame for efficient storage and manipulation of labeled/columnar data Matplotlib includes capabilities for a flexible range of data visualizations Scikit-learn helps you build efficient and clean Python implementations of the most important and established machine learning algorithms